Researcher · Founder · Ph.D., IIT Delhi

Siddharth
Srivastava

Learning to see, understand,
and build with AI.

I work on computer vision and multimodal learning: how models represent the world, generate visual content, and become useful AI systems.

I founded OmniTensorLabs, where I work on multimodal systems, agents, and evaluation. I also advise Timble AI, where I previously served as CTO.

Previously, I was AI Architect / Director of ML at Typeface. I co-founded TensorTour as CTO; Typeface acquired the company in 2024.

At C-DAC, I led national electoral search across 900M+ voter records and provided technical leadership for e-RaktKosh, serving 2,100+ blood banks by 2021.

1,171 citations 18 h-index 22 i10-index

Google Scholar · All-time metrics ·

Siddharth Srivastava
SiddharthResearch & building

Selected research

Represent. Generate. Generalize.

Three threads through my work: efficient 3D representations, controllable generation, and learning across modalities.

CVPR2026
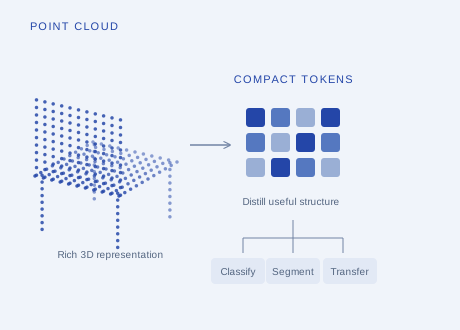
Concept: distill a 3D point-cloud representation into compact tokens for multiple tasks.
Concept illustration · 3D representation distillation

3D vision / Efficient foundation models

Foundry

Distilling 3D Foundation Models for the Edge

How much of a 3D foundation model can a smaller model retain? Foundry compresses rich point-cloud representations into compact tokens, preserving their usefulness across downstream tasks.

Guillaume Letellier, Siddharth Srivastava, Frédéric Jurie, Gaurav Sharma

ICCV2025
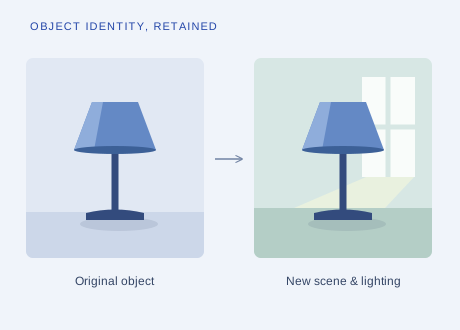
Concept: the same lamp remains recognizable as its scene and lighting change.
Concept illustration · Same object, new composition

Generative AI / Object preservation

Preserve Anything

Controllable Image Synthesis with Object Preservation

Changing a scene should not change the object that matters. This work studies controllable image synthesis that preserves an object while adapting its surroundings, composition, and lighting.

Prasen Kumar Sharma, Neeraj Matiyali, Siddharth Srivastava, Gaurav Sharma

CVPR2024
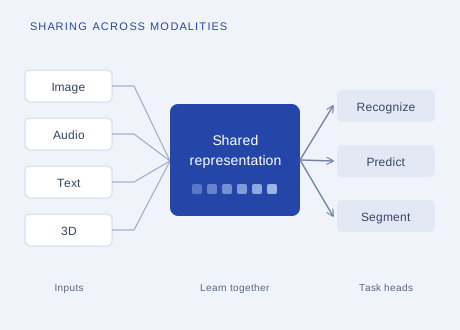
Concept: image, audio, text, and 3D inputs share a representation used by different tasks.
Concept illustration · Learning across modalities

Multimodal learning / Shared representations

OmniVec2

A Novel Transformer Based Network for Large Scale Multimodal and Multitask Learning

Can different modalities benefit from learning together? OmniVec2 combines modality-specific input processing with a shared transformer and task-specific heads, extending the cross-modal learning explored in OmniVec.

Siddharth Srivastava, Gaurav Sharma

More selected publications

For the full publication list and citations, visit Google Scholar.

Current work

Ideas you can explore.

Alongside publications, I build tools for developing AI systems, evaluating their behavior, and understanding the research landscape.

Research & products

OmniTensorLabs

My lab’s work on visual, multimodal, and agentic intelligence, connecting research questions with working demonstrations and AI products.

Explore the lab

Open-source evaluation

Multivon

A Python library for evaluating AI systems. Bringing repeatable evaluation into the process of building models and agents.

Explore Multivon

Research exploration

ConferenceScope

An interactive view of topic trends across major machine learning conferences, built to make the literature easier to navigate.

Open dashboard

From the notebook

Recent updates.

Earlier updates
  • Shared the Foundry preprint.
  • OmniVec2 published at CVPR.
  • OmniVec published at WACV.
  • Paper accepted to IEEE ICIP 2023.
  • Recognized as a CVPR Outstanding Reviewer.
  • Papers accepted to CVPR and ICRA.

Let’s connect.

I’m happy to hear from researchers, engineers, founders, and anyone interested in the work.

Connect on LinkedIn